At the beginning, there was one machine.
One server ran our database and web application.
But as our database began to scale, we needed to separate them.
Separating the servers is easy - Just define an 'internal' network, and let the machines communicate via the internal leg.
However, this caused another problem - We began to experience long lags when transferring large datasets between the machines.
When dataset was larger than X items, performance began to degrade, and was substantially slower due to network lag. Below that, performance was actually better.
Part of it was due to node's mysql drivers. They're just slow. (Compared to native mysql drivers)
The other part was network lag.
So how do you solve it?
Part of my original design was using mysql as a data store - Only use simple sql, no arithmetical operations and aggregations. This allowed us to move from mysql to mongodb easily, and eased CPU load for the database.
But now it's time to shift the weight, because bandwidth is our new bottleneck.
So we're moving some of the heavier processing into the database so that a smaller dataset would transfer faster. Much faster.
Performance is a delicate art of balance. Always remember that paradigms change as scale changes. Don't be afraid to shift weight in order to keep your system balanced.
Thursday, August 21, 2014
Sunday, July 27, 2014
Recruitment - A different take
Growing as a company could sometimes be difficult.
You need to be able to recruit people (Or outsource them, which will not be handled in this post), train them and get them to be productive as fast as you can.
For a small startup, this is even harder - Every position counts, and every worker might be responsible for great success, or miserable failure. This can make the recruitment decision a very critical one.
For our next recruit, which should be a tier 3 support engineer, we've decided to handle the process a bit differently.
First, we decided to describe the typical workday for the position. What the person would do when he comes to the office, which would be his tasks, how would he work. We write that down.
After that analysis, we focus on what he (Or she) needs to know in order to perform his tasks. It could be deep knowledge of our product, SQL know how, MS Office skills or whatever. Divide those skills into skills he would need to know "From home", generic skills that could be taught, and specific (Our product) know how.
Once we know that, we can actually start looking for the right person. The search would be much more focused, as a lot of skills which you might consider as prerequisites will be shed during the process.
We would also have a clear training plan for that person.
In the end, I love to say that I'm looking for excellent PEOPLE - As most skills could be taught.
Happy hunting!
Monday, May 19, 2014
Behold, the future!
This week, I've spent two days at the Google TLV Campus, participating in an amazing workshop given by Prime design studio.
Though I'll probably cover the workshop in another post (Waiting for 'official' photos), I would like to share one significant insight I've got:
During brainstorming for our workshop project's specs and features, Omri (Prime's CEO) sat with us, and while we were looking at a certain concept, asked us to look forward to the future of that product. What would such a product do 10 years from now? 20 years?
So we sat down, throwing down sci-fi inspired ideas ranging from laser grids and quad-copters to terra forming robots (Yes, it was THAT crazy).
[Side note] The two basic rules of brainstorming are: Write down everything, and never argue. Anything is possible during brainstorm, even the most ridiculous ideas.
After that, we looked at the result, and understood what we'll be working on. And though it was different from the original project and looked a bit like a moon shot, it started to seem possible, and the end result (And presentation) was awesome.
After contemplating on the whole process, I've come to realise that we almost never look at our product 10 years from now.
And we should, because a lot of those features could be implemented today.
Successful companies are great at this, because they create the future of products now. The best example is Apple, but in a smaller scale, Waze, Nest and 23andMe are great examples as well.
Show your customers the future they want, and you will own it.
![]() |
| The future, according to us. Visioned product is top left. |
Thursday, May 8, 2014
No, you are not like us.
There's a time in a person's career where he is either managed by younger people, or managing younger ones.
Nearing 40, you begin to develop a generational gap with some of your surroundings. Either you need to recruit younger talent, work with (Or report to), or manage younger people. This has all happened to me before, nevertheless, a gap of more than 10 years means a generational gap.
I might hang out in the same social networks. Maybe even (If you're still) go out to the same cool places, or like the same music. I may even look younger than your real age (Of course I do, and so do you! :)).
But still, I'm older. Which means that (If you look at it in reverse), I might as well be 120 to them.
I won't go into sociological terms like the 'x'/ 'y'/ whatever generation, but as far as I know, the two best things you can do are:
- Don't think you are 'one of them'. Acting/ behaving/ chasing habits won't make you younger. It will be like my mom getting into Instagram and starting to post comments on every one of my kids' pictures, backwards to one year ago. Just don't.
- Do try to understand the culture. The habits. The language. Much like understanding the recent buzz tech tool or design language, you do need to keep up, just keep up in your own terms, pace and perception.
Wednesday, April 23, 2014
Reading time #6!
All right, 6th time around, some good reads and links.
- Was Better place a revolutionary startup, or a huge flop just waiting to happen? (Personally, I was sceptical from the beginning... But this is just me) This is the most amazing article documenting the huge car business that never happened.
- Here's my friend Moshe Kaplan's view of our Mysql to Mongo migration process. Article was favoured by MongoLabs themselves. Respect.
- If any of you is into creating cool stuff with HTML5 canvas, you MUST check out obelisk.js. So cool.
- I've been talking a lot about node and mongodb - Feel like getting started? Here's one great step by step tutorial on writing your first node/mongodb web service.
- A nice little service to create and share youtube mixtapes - This one is on beta, but looks promising.
And, finally (And a little off topic), two shows to watch:
- If you've ever been near a startup, you MUST watch Silicon Valley. Made by Mike Judge (Yes, the one who created Beavis and Butthead).
- Being a teen in the beginning of the 90s wasn't easy. Surviving Jack shows how teens communicated BEFORE mobile tech and social network existed.
Previous reads:
#5
#4
#3
#2
#1
Friday, April 4, 2014
Clear off the table
[ taking some time off the ongoing mysql->mongo series ]
Been visualising data a lot lately.
Scatter charts, realtime indicators, good ol' line charts and, of course, tables.
It's really easy to fill the screen with loads of information, screaming colours and as many numbers floating around the screen. This makes orientation difficult for the user, especially non-technical users.
Some of our users simply need insights and recommendations, but need the graphs for credibility.
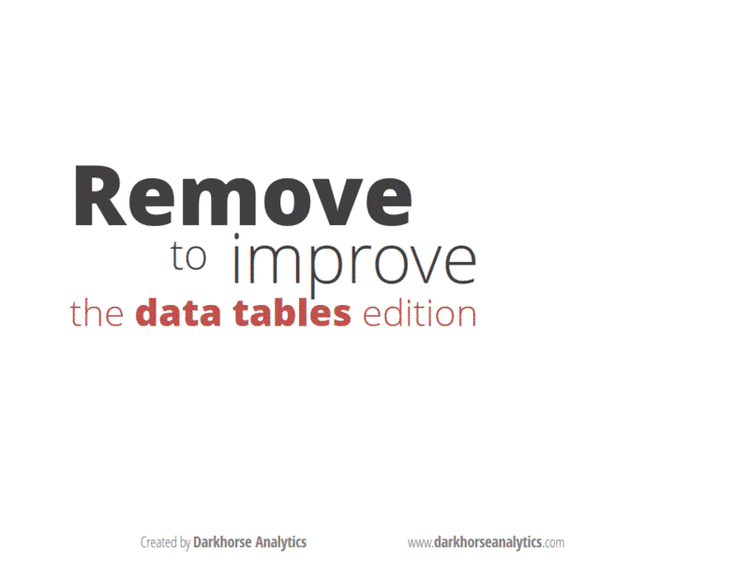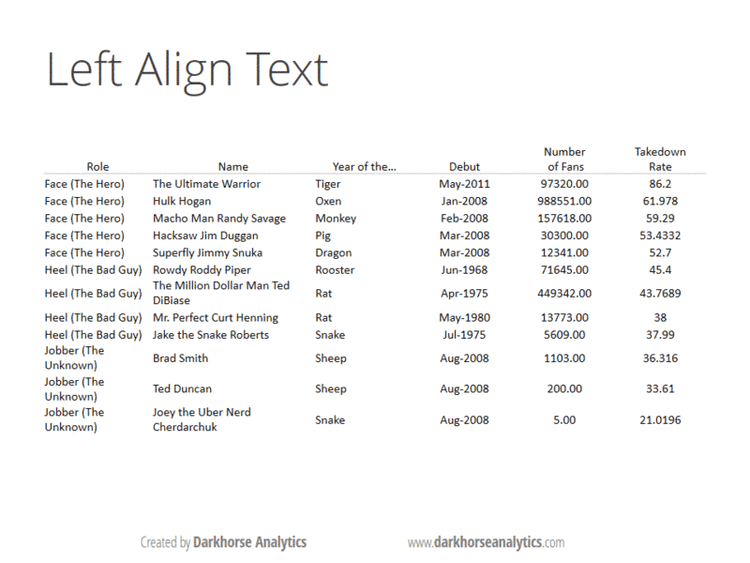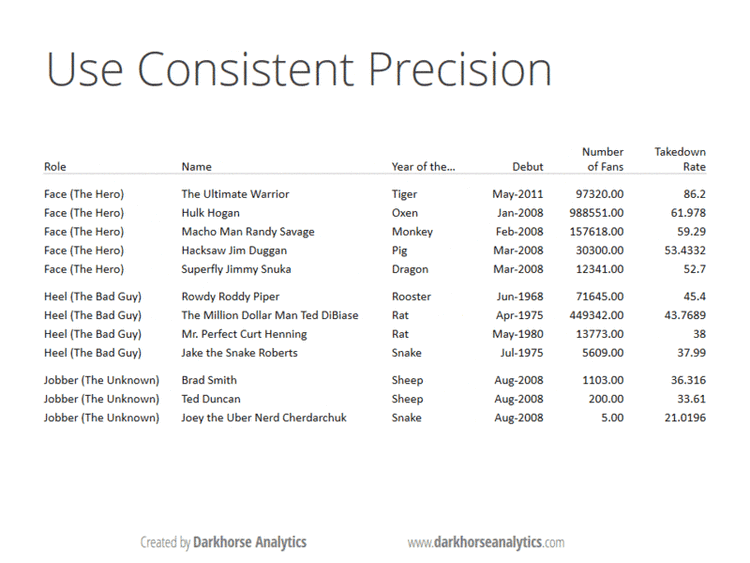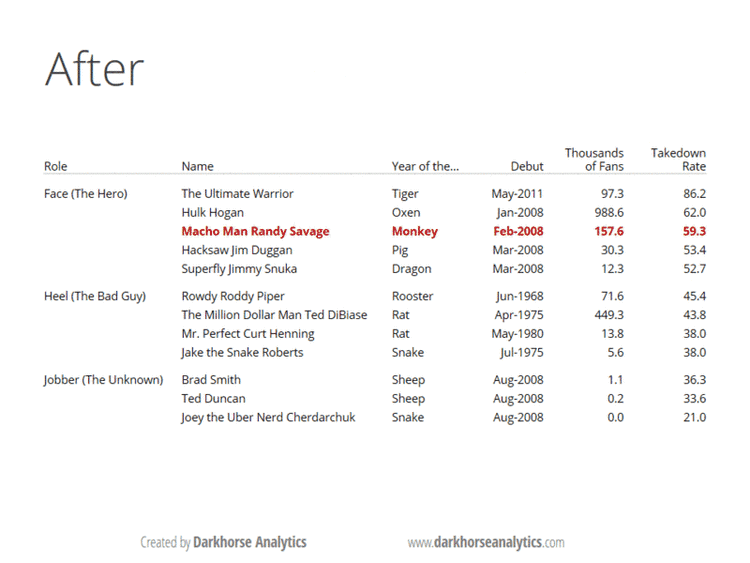
This is a great post from darkhorseanalytics explaining how a good table looks like. [hint - not your good ol' office 1998 excel highlight table]
http://darkhorseanalytics.com/blog/clear-off-the-table/
Sunday, March 30, 2014
Mysql to MongoDb, chapter 2: Diving in
[This is a second part in an ongoing series, part 1 is here)
So, after making the call to go mongo, doing a mongo 101 crash course, we've started working on two major fronts (Only two developers):
1. DB Layer rewrite - This was pretty much straight forward. We've had about 100 functions to rewrite, but a lot of them were simple CRUD function. We've decided to use the native mongo node drivers, as I don't like to use frameworks in my code. (There's mongoose, which is a nice ODM layer, but, as I've said, I'd rather use native stuff, unless there's a performance advantage there.)
Major points you need to consider when transforming your code:
- Mysql has auto count features for unique inserts in table. Mongo has a unique id per object in database. If you're not using one, single unique id (And you're not) for each record in your mysql database, you need to use some sort of an applicative counter solution for inserts in mongo. This is also very useful to return insert id for new entities.
- Type checks and conversion: Rather than using a framework, I've decided to implement a simple hash table for field names and types.
- Logging: Like printing mysql statements to log, write a function which logs your query objects in mongo native format. (Like db.users.find({name:"yuval"}). It makes it much easier to debug.
2. Data conversion - We used mongify, a neat ruby tool, which translates sql databases into mongo. Performance was a bit dodgy for huge tables, se we've contributed some code, which also upped the performance by ~20 times.
Some things we've encountered during our conversion process:
- Dry run your conversion process. Dump your mysql, reload into a vanilla server with mongo installed, and do the dry runs from that server. The operational conversion is something you only need to do once, so it's ok to leave things for manual tinkering later!
- You'll see your application is working slower. Don't worry about it. There's a lot of tuning to do.
- Indexing: You need to take good care of this. Use explain({verbose:1}) for your big queries in order to find out why. Indexing in mongo will solve a lot of your performance problems.
- Large sorts won't work, even with indexes. In our case, it was a sort for an set of more than 130000 records. Instead of implementing paging, we've moved the sorting to the application (Works really fast, thank you). We will need to implement paging eventually, because we've just postponed the inevitable...
- Uniqueness: Like mysql, mongo has an ensureUnique method on index creation. We decided to add indexes manually and not automatically.
The next chapter will deal with more sophisticated tuning methods post conversion. Stay tuned :)
So, after making the call to go mongo, doing a mongo 101 crash course, we've started working on two major fronts (Only two developers):
1. DB Layer rewrite - This was pretty much straight forward. We've had about 100 functions to rewrite, but a lot of them were simple CRUD function. We've decided to use the native mongo node drivers, as I don't like to use frameworks in my code. (There's mongoose, which is a nice ODM layer, but, as I've said, I'd rather use native stuff, unless there's a performance advantage there.)
Major points you need to consider when transforming your code:
- Mysql has auto count features for unique inserts in table. Mongo has a unique id per object in database. If you're not using one, single unique id (And you're not) for each record in your mysql database, you need to use some sort of an applicative counter solution for inserts in mongo. This is also very useful to return insert id for new entities.
- Type checks and conversion: Rather than using a framework, I've decided to implement a simple hash table for field names and types.
- Logging: Like printing mysql statements to log, write a function which logs your query objects in mongo native format. (Like db.users.find({name:"yuval"}). It makes it much easier to debug.
THIS ONE IS REALLY IMPORTANT:
Do not break mysql support in order to support mongo! Fix both the mysql and mongo db layers, not in your application layer! Make it work, and don't do irreversible things that would brake mysql support. Support switching form mysql to mongo in a single configuration flag, so you can compare performance.
2. Data conversion - We used mongify, a neat ruby tool, which translates sql databases into mongo. Performance was a bit dodgy for huge tables, se we've contributed some code, which also upped the performance by ~20 times.
Important note for people using open source software - Don't just report bugs. You can fix stuff and contribute to the community.
[Especially if you're using it for commercial purposes]
Some things we've encountered during our conversion process:
- Dry run your conversion process. Dump your mysql, reload into a vanilla server with mongo installed, and do the dry runs from that server. The operational conversion is something you only need to do once, so it's ok to leave things for manual tinkering later!
- You'll see your application is working slower. Don't worry about it. There's a lot of tuning to do.
- Indexing: You need to take good care of this. Use explain({verbose:1}) for your big queries in order to find out why. Indexing in mongo will solve a lot of your performance problems.
- Large sorts won't work, even with indexes. In our case, it was a sort for an set of more than 130000 records. Instead of implementing paging, we've moved the sorting to the application (Works really fast, thank you). We will need to implement paging eventually, because we've just postponed the inevitable...
- Uniqueness: Like mysql, mongo has an ensureUnique method on index creation. We decided to add indexes manually and not automatically.
The next chapter will deal with more sophisticated tuning methods post conversion. Stay tuned :)
Subscribe to:
Posts (Atom)